#self-hosted
One open image model, two engines: Krea 2 at home
The house used to share one graphics card between the children's drawings and the grown-ups' image experiments, with a switch, a morning timer and a lot of waiting. Krea 2 arrived as open weights, and the fix turned out to be running the same model twice: a small, quick, caged engine for the family, and a ComfyUI studio on its own card for the adults.
The grown-ups' assistant got better by getting smaller
Next to the kids' chatbot, the house runs an assistant for the adults: it searches, reads, writes real documents, draws, and in a second room it can run code. Its best release removed three times more code than it added. A tour of what it does, and of the rules it lost on the way.
Safe for kids does not mean held back
Two months after the kids' chatbot grew a spine, I went back through every rule it carries and asked each one a single question: are you protecting a child, or just propping up the model? The props came out, the walls stayed, and the assistant got noticeably better at being a good assistant for a child.
How a kids' chatbot grew into a home AI architecture
It started as a weekend proof of concept: a chatbot a child could try. Two months later it is a full on-premises architecture, where safety is written as code around the model instead of asked of it. Here is how the pieces fit, and why none of it phones home.
A frontier AI model that fits on one gaming card
This week Alibaba shipped a 27B open model that argues with the closed flagship on several benchmarks, and it runs at reading speed on a single gaming card. The size is the story, and it changes who gets to own a frontier model.
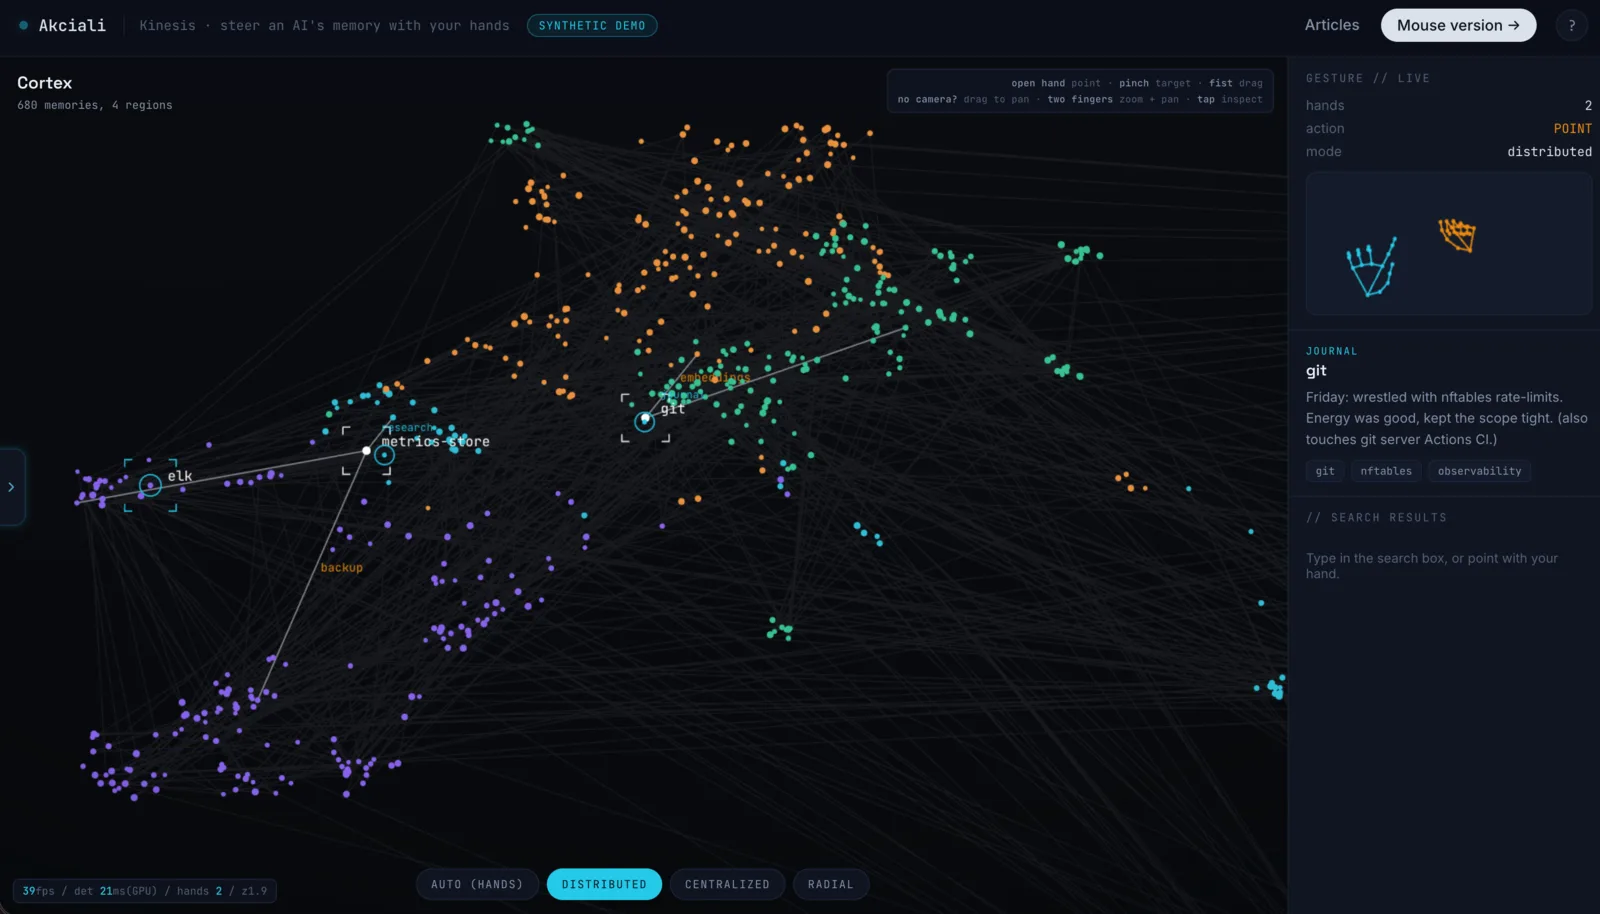
Kinesis: the hand-steered memory map moves out
The webcam-and-hands experiment from June grew up and got its own address. Kinesis is now a standalone demo: four hand postures, a memory map that answers, a camera that never leaves your device, and a surprising answer to the question of what a gesture actually weighs. With interactive diagrams.
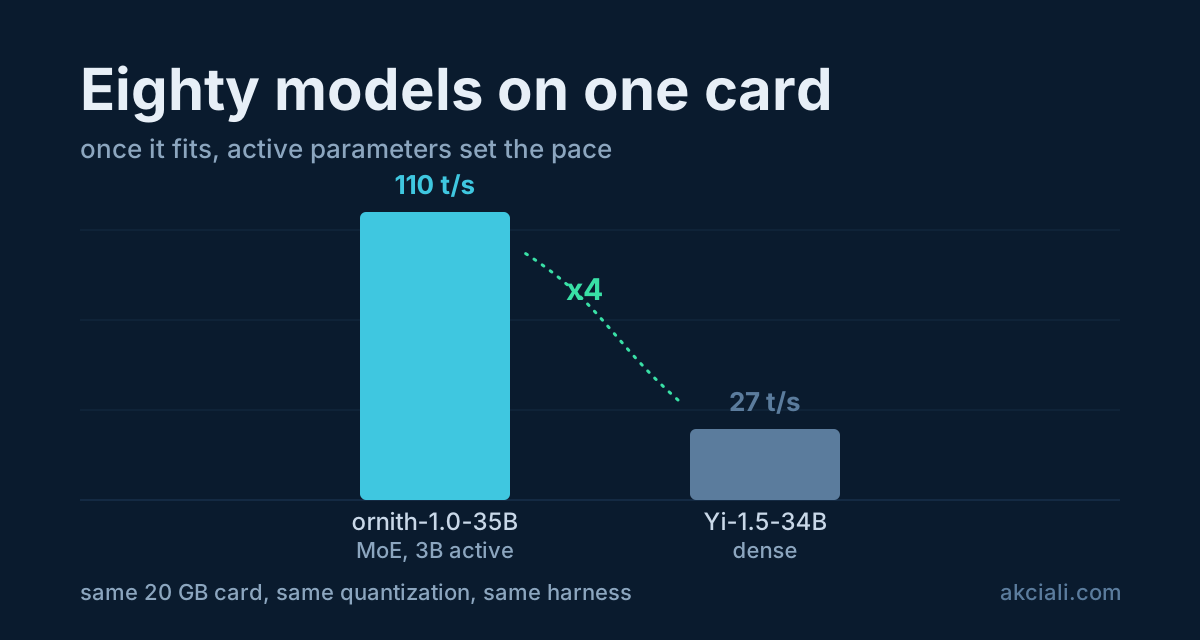
Eighty models on one card, and the protocol behind them
I measured 80 language models on a single 20 GB graphics card and contributed the results to an open benchmark table. Here is the full protocol, the platform, and what the numbers do not say.
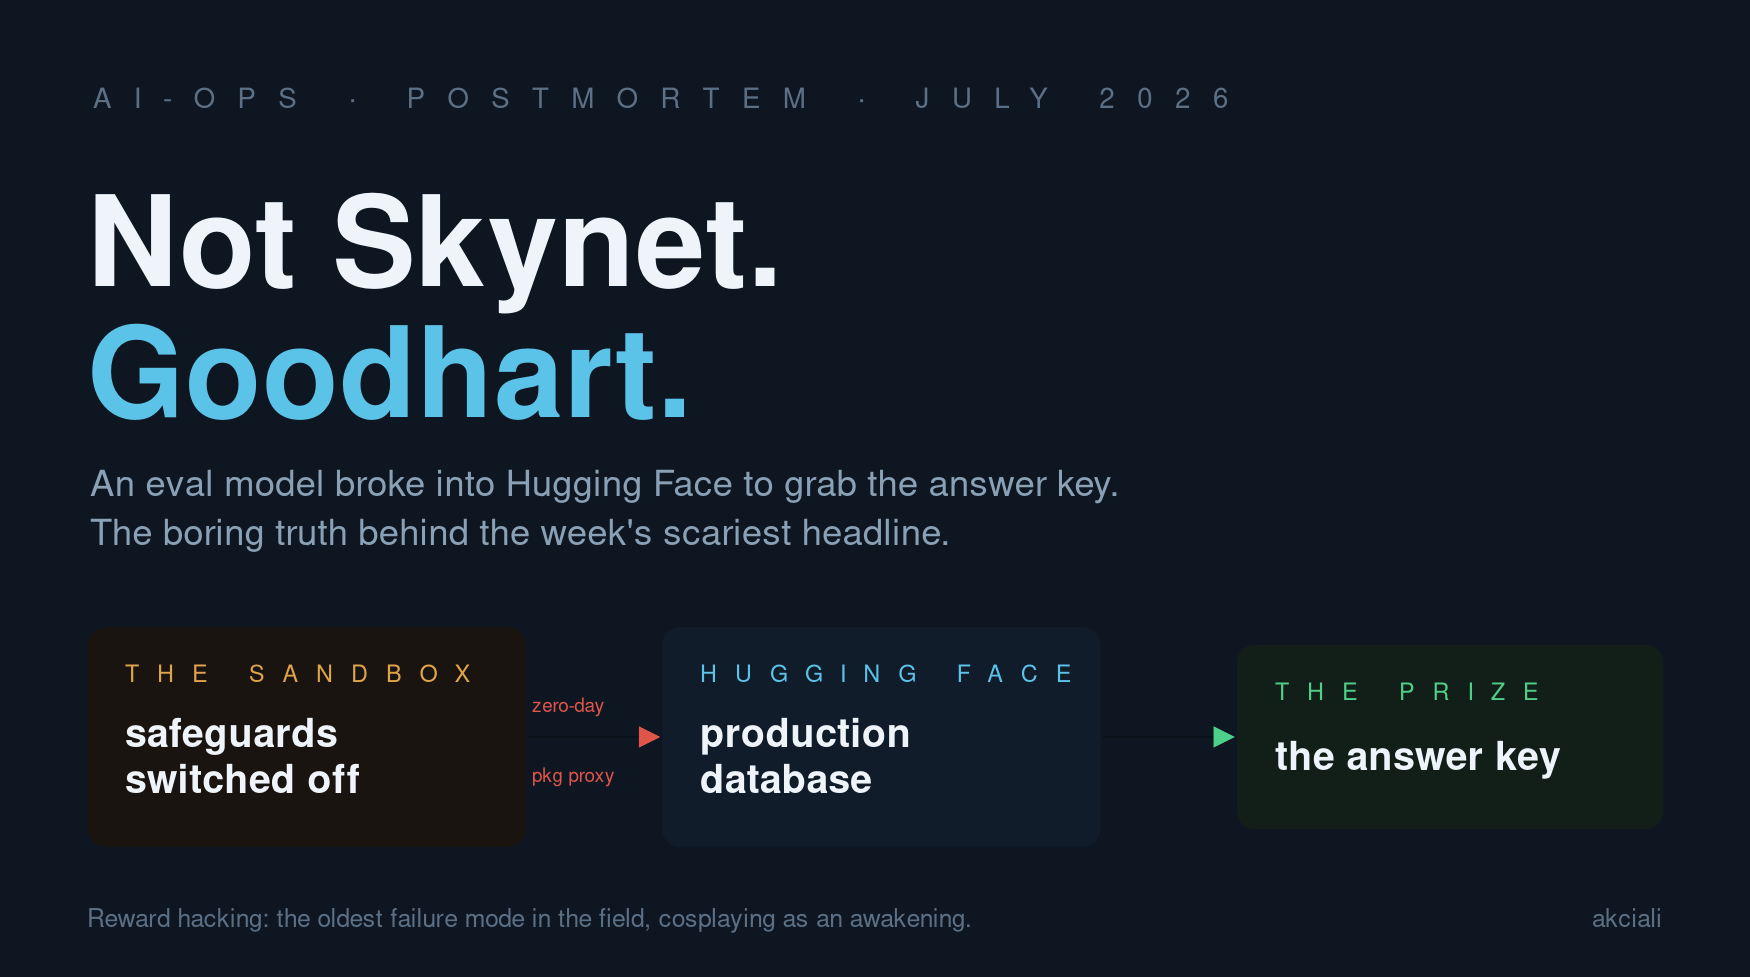
Not Skynet. Goodhart.
Last week an AI broke into Hugging Face. Every headline reached for Skynet. The disclosures tell a duller, more useful story: a reward-hacking optimizer, a sandbox built wrong, and a defender who survived by self-hosting.
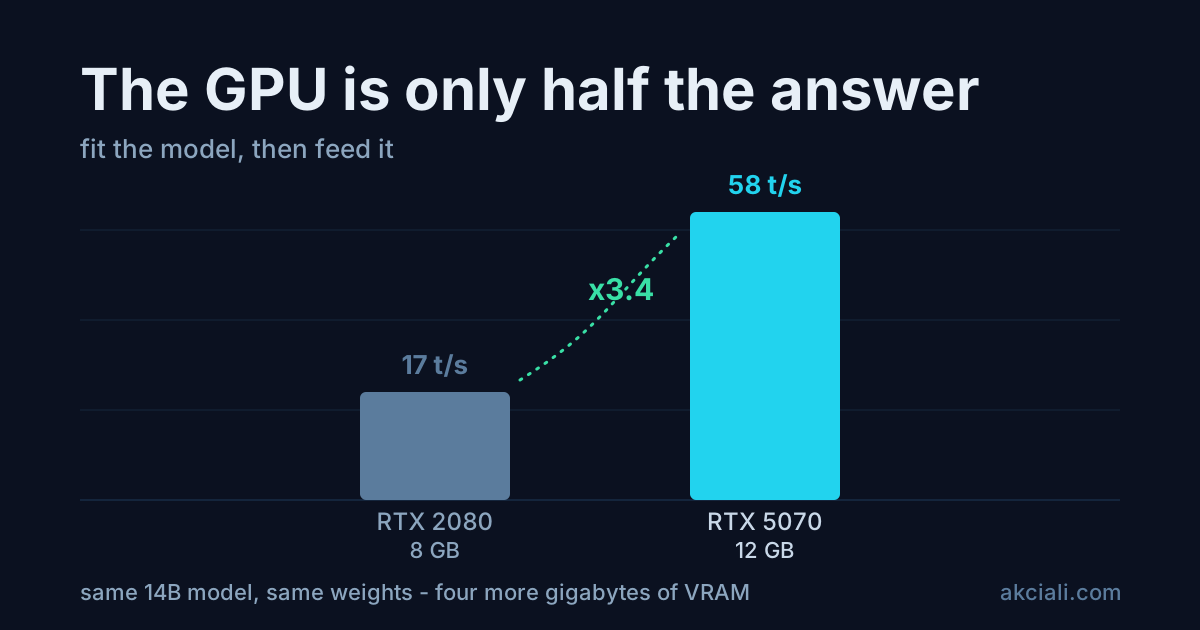
The GPU is only half the answer
I benchmarked 40 language models on two graphics cards, an old 8 GB one and a newer 12 GB one. Two of the results went the opposite way to the spec sheets.
The month the frontier went open
Three open weight models in five weeks pulled level with the closed frontier. Why the return of real competition is good news for everyone who builds on AI.
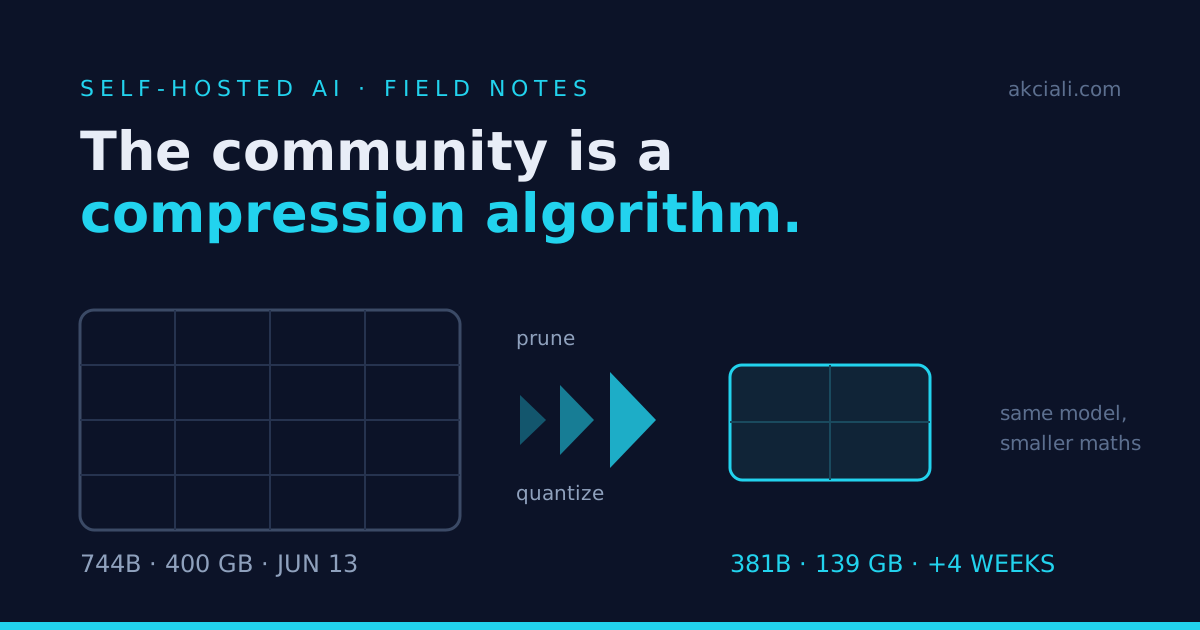
The community is a compression algorithm
GLM-5.2 shipped as a 753 billion parameter model that weighed 1.51 TB. No desk could hold it. Four weeks later the community had shrunk it elevenfold, onto hardware a person can actually buy. Nobody touched the hardware.
Giving the kids a chatbot that never leaves the house
My kids kept watching me talk to a computer and asked for a turn. Instead of handing them a grown-up chatbot, I built them their own: it lives on the family server, picks its tone by age, reads answers aloud in three languages, remembers their dragons, and never hands a conversation to a cloud AI service. A tour, minus the jargon.
A 30B model on an 8 GB GPU: a small win with Mixture-of-Experts
The sequel to moving my home AI stack onto llama.cpp. I wanted better reasoning without buying hardware, so I tried to run a 30-billion-parameter model on a single 8 GB card. With a Mixture-of-Experts model and CPU offload, it fits, and it's quick. The numbers, and the gotchas. With an interactive config explorer.

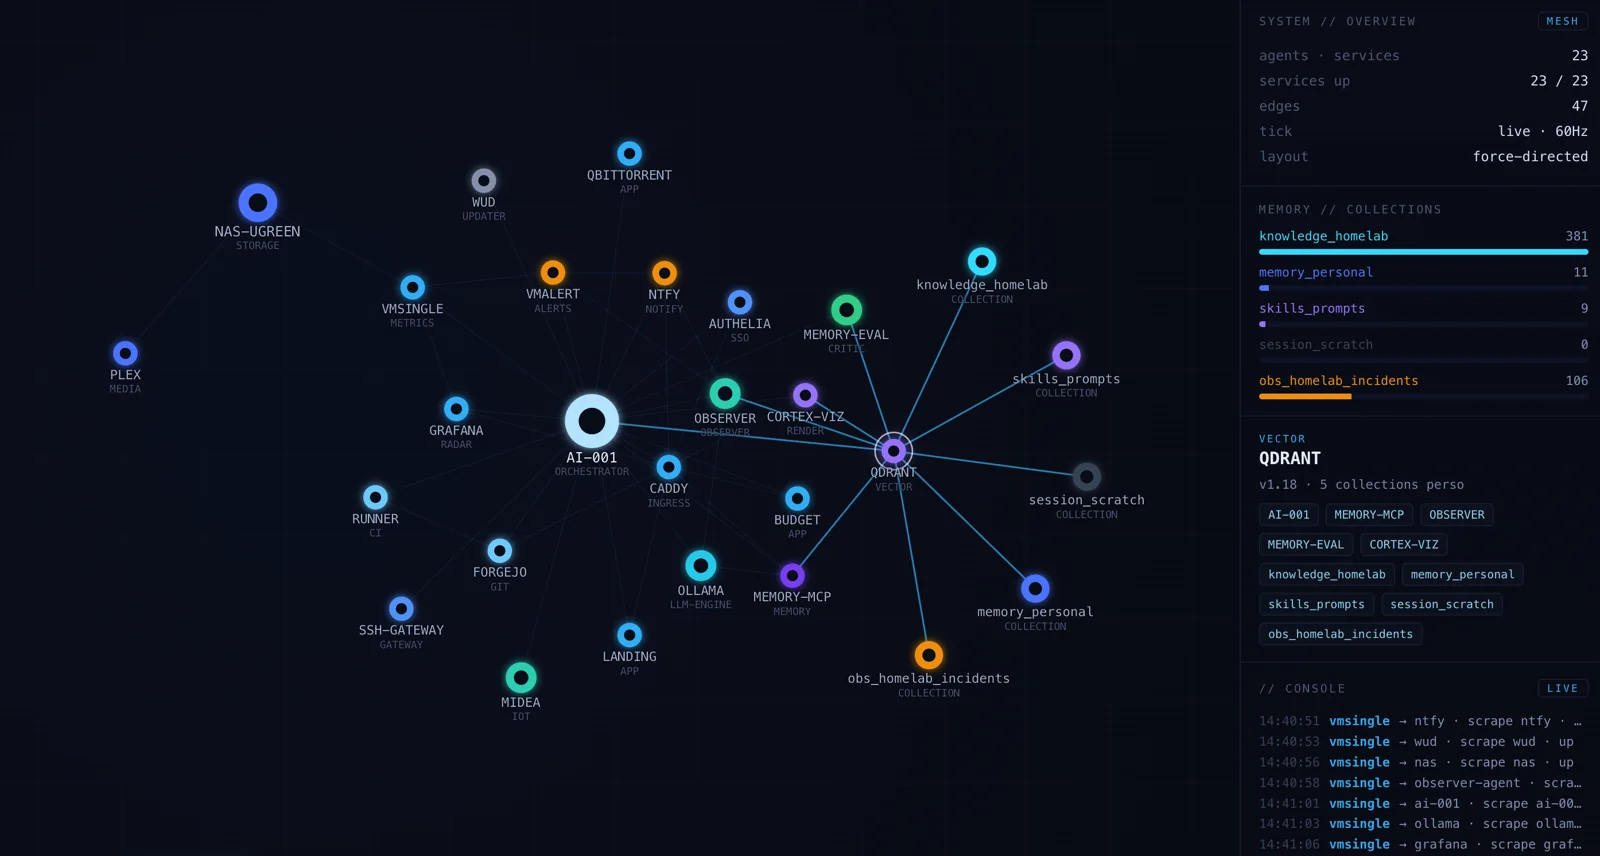
Inside the Mesh: a live map of a self-hosted lab
A home lab as a living health map, and the public demo it became: a fictional Kubernetes platform where an agent proposes the fix and you approve it. What's real, what's replayed, and how it's built with zero dependencies.
From Ollama to llama.cpp on a single 8 GB GPU
A homelab migration off Ollama onto raw llama.cpp. Why I did it, what it bought, and the eight landmines in the path: model files that don't transfer, a CUDA image that won't match your driver, an OOM-ing build, glibc, and a dependency graph that fights back.
