#gpu
A frontier AI model that fits on one gaming card
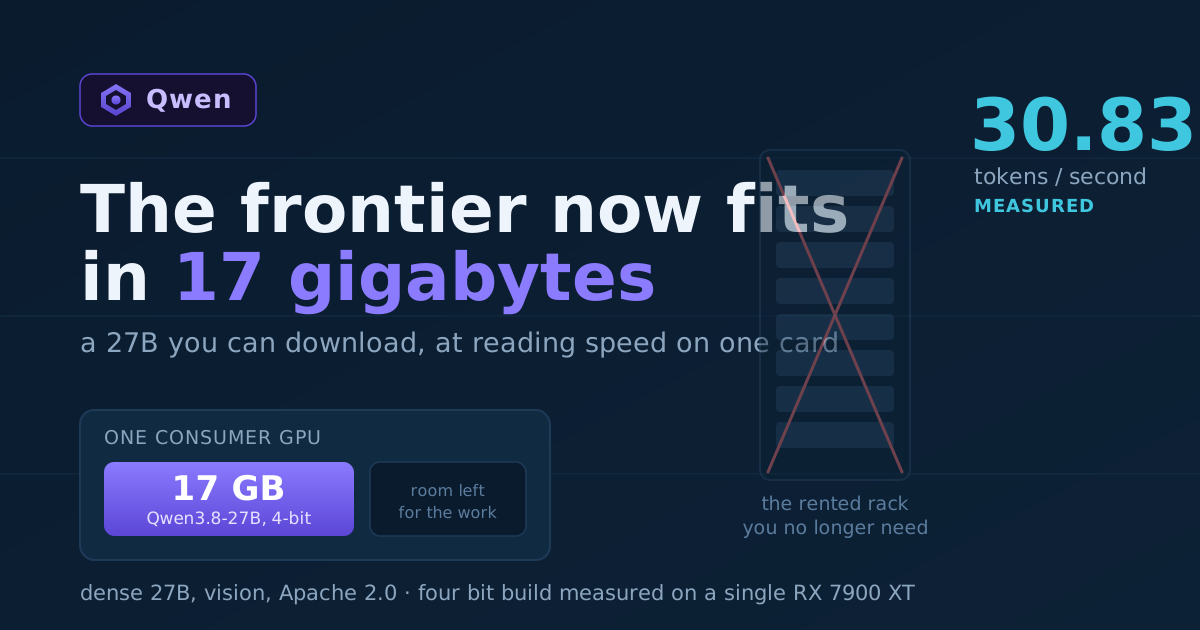
This week Alibaba shipped a 27B open model that argues with the closed flagship on several benchmarks, and it runs at reading speed on a single gaming card. The size is the story, and it changes who gets to own a frontier model.
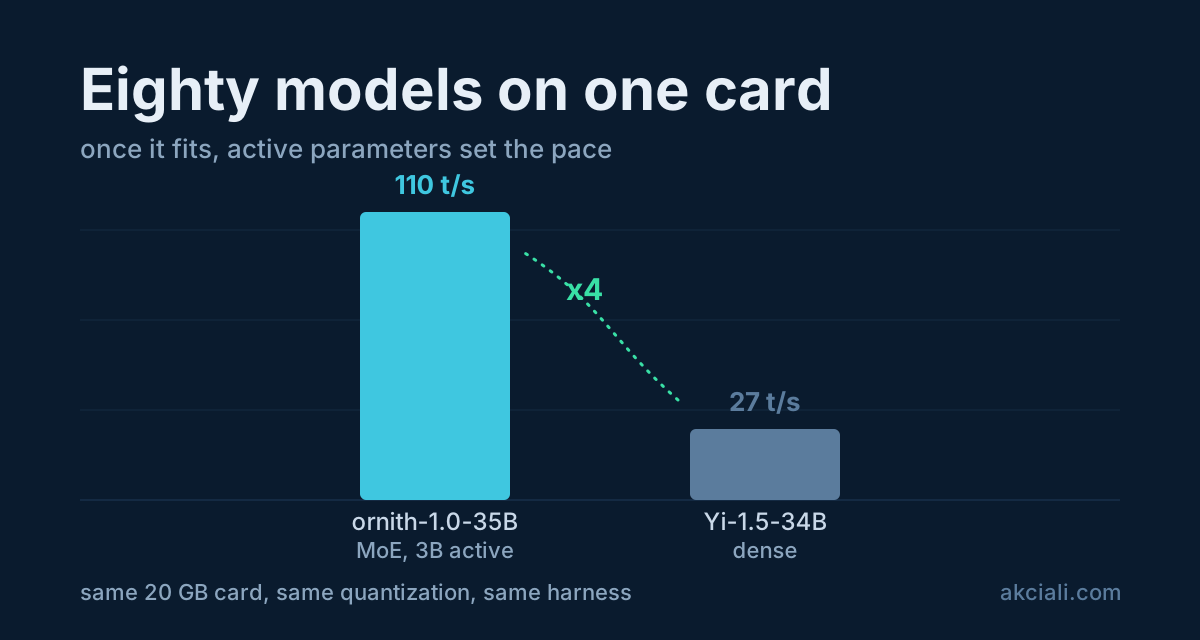
Eighty models on one card, and the protocol behind them
I measured 80 language models on a single 20 GB graphics card and contributed the results to an open benchmark table. Here is the full protocol, the platform, and what the numbers do not say.
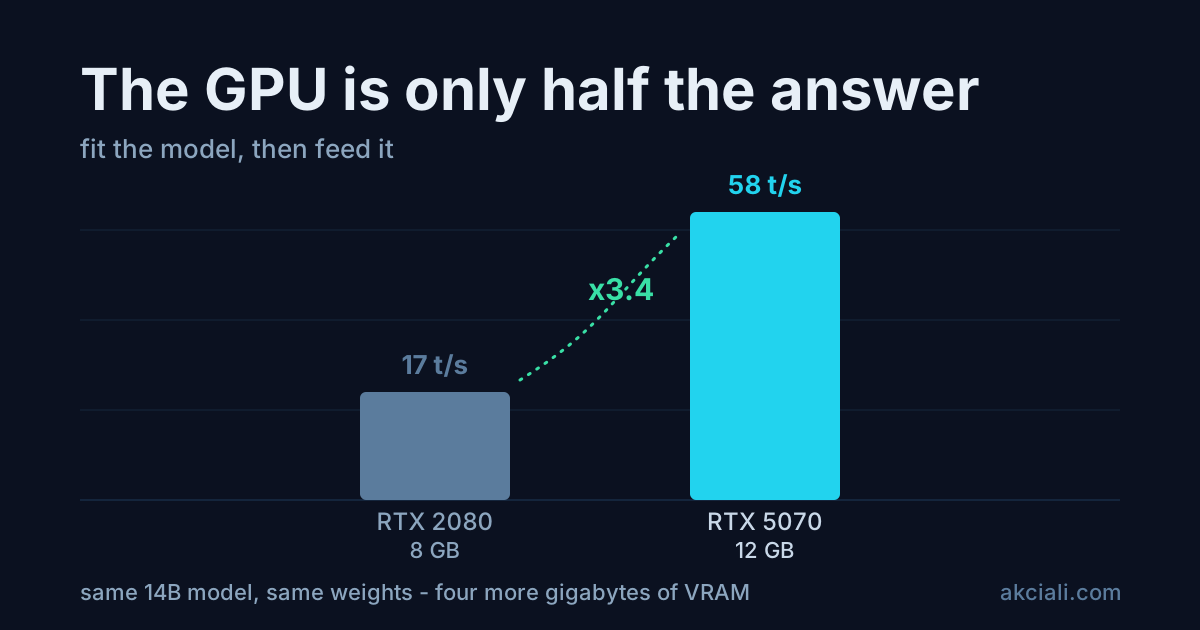
The GPU is only half the answer
I benchmarked 40 language models on two graphics cards, an old 8 GB one and a newer 12 GB one. Two of the results went the opposite way to the spec sheets.
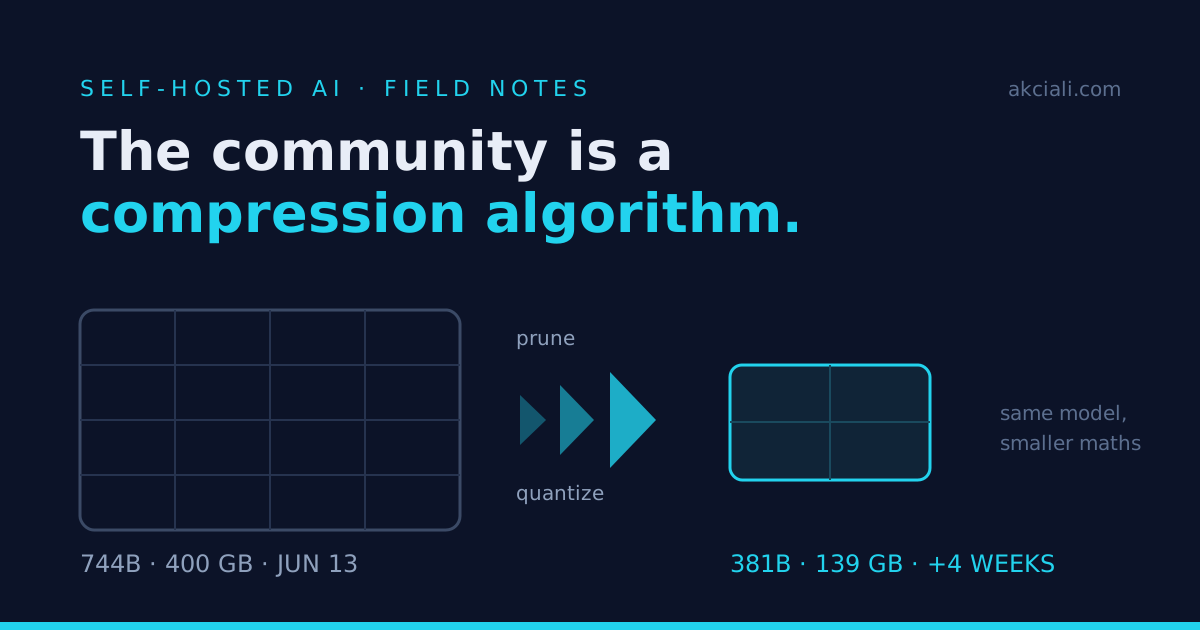
The community is a compression algorithm
GLM-5.2 shipped as a 753 billion parameter model that weighed 1.51 TB. No desk could hold it. Four weeks later the community had shrunk it elevenfold, onto hardware a person can actually buy. Nobody touched the hardware.
A 30B model on an 8 GB GPU: a small win with Mixture-of-Experts
The sequel to moving my home AI stack onto llama.cpp. I wanted better reasoning without buying hardware, so I tried to run a 30-billion-parameter model on a single 8 GB card. With a Mixture-of-Experts model and CPU offload, it fits, and it's quick. The numbers, and the gotchas. With an interactive config explorer.

From Ollama to llama.cpp on a single 8 GB GPU
A homelab migration off Ollama onto raw llama.cpp. Why I did it, what it bought, and the eight landmines in the path: model files that don't transfer, a CUDA image that won't match your driver, an OOM-ing build, glibc, and a dependency graph that fights back.
